An AI answer recommends a competitor and leaves out your brand. Before asking your website team for another page, you need to know what the answer actually shows—and whether a change would address it. That is the practical test for GEO, or generative engine optimization: can an audit of AI answers help you decide what deserves work?
The short answer: rarely, in these records
Of the five dedicated GEO products we compared, only Peec AI produced tasks that met our standard, and only for six of nine brands. ChatGPT, the general assistant your team may already pay for, did better when asked directly for changes with evidence and a way to check them. For a first audit, it may be enough already. But every change it proposed concerned the brand’s own pages; none addressed earning citations elsewhere. The comparison rests on one saved batch per product.
The verdict: start with ChatGPT for a first audit
For a brand or growth lead doing an initial audit, ChatGPT is our first tool to trial. It had the highest composite score at all nine brands. Its clearest lead is on questions and diagnosis: scored on those two tasks alone, it reaches 96.0 against Writesonic’s 83.8. Writesonic came close on diagnosis; Peec AI was the only dedicated tool to earn action credit.
Two conditions shape that result. Weigh them before relying on it:
- ChatGPT’s prompt matched the rubric. It was asked for up to three actions, each with a target, specific action, supporting evidence, feasibility and validation. Our rubric credits an action when it has a target, a change, evidence and a result check. The dedicated tools received no equivalent instruction, and Writesonic’s zero action score comes from missing result checks. Part of the action gap therefore measures who was asked for that field.
- OpenAI appears on both sides. ChatGPT is an OpenAI product, and OpenAI’s own website is one of the nine brands audited.
The useful result is a website task a colleague can trace to a saved answer, check against the business and accept, revise or reject. The cases below show ChatGPT getting closer to that result—and where even its advice needed correction.
This recommendation covers recorded analysis workflows only. Monitoring, team reporting, costs and business outcomes need a separate evaluation.
The ranking
The comparison covers 54 product–site records: six products across nine brands, each from one recorded batch. Run dates and subscription plans were not consistently recorded.
This is the results chart at the top of this page ↑
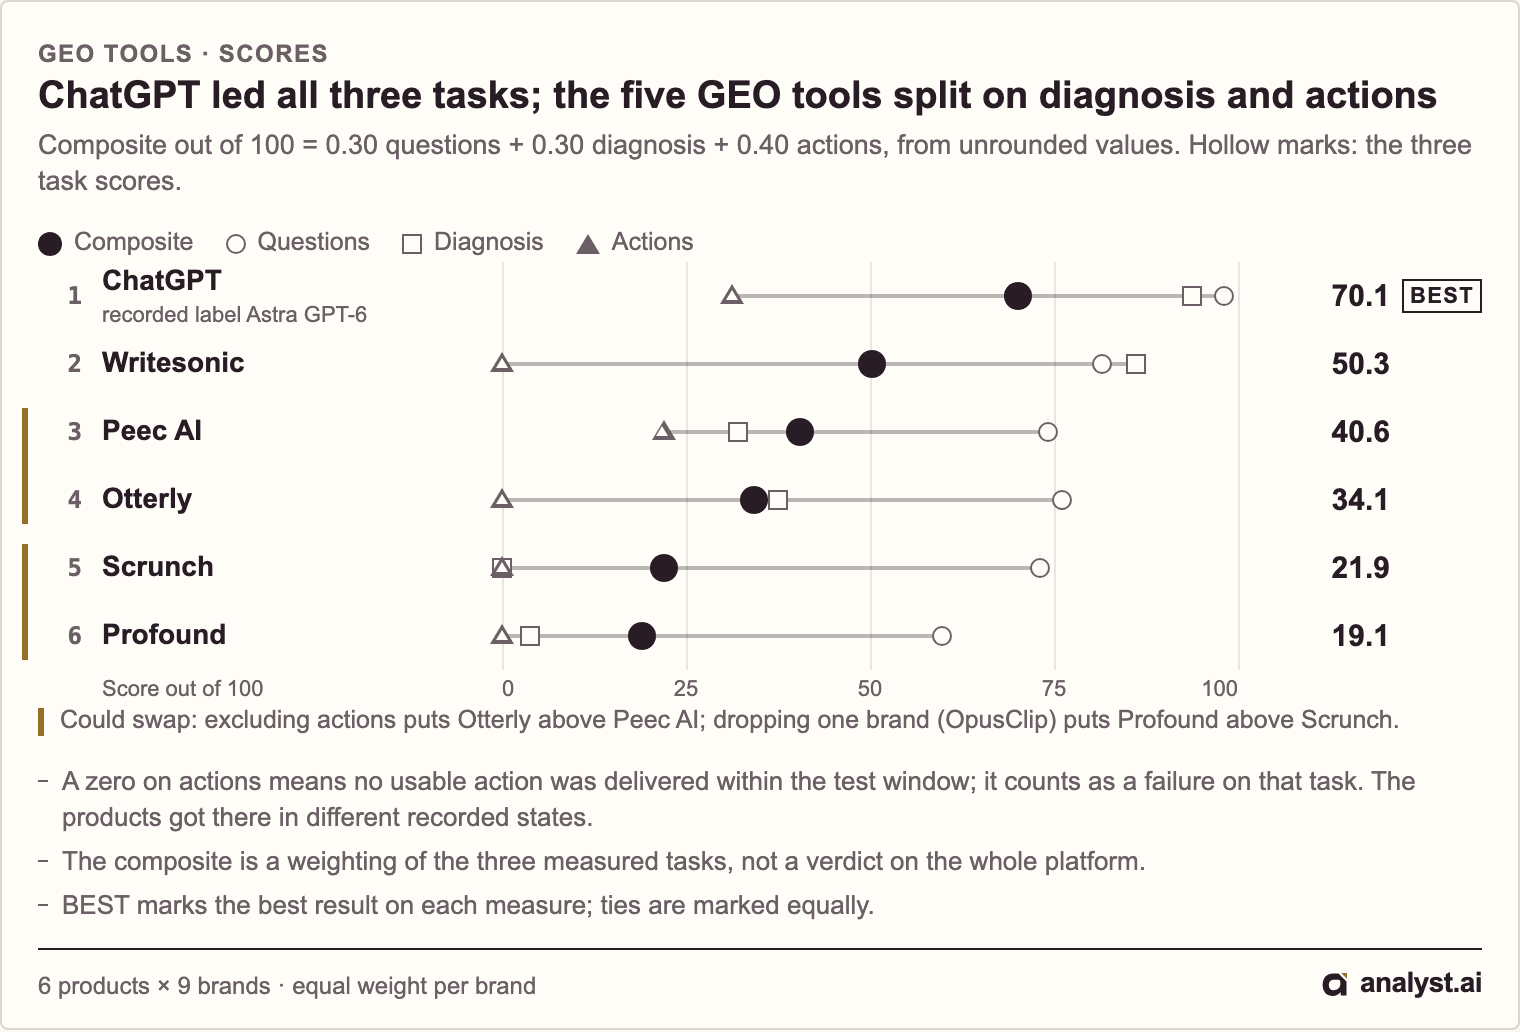
Read the ranking in tiers. ChatGPT ranked first at every site, with site composites between 68.1 and 73.3. Writesonic ranked second at seven of nine. Places three to six are not robust: Otterly moves above Peec when actions are excluded, and Profound moves above Scrunch when one site is dropped.
Zero action scores also mean different things: delivered advice that missed the criteria (Writesonic), incomplete output (Otterly) or a waiting state with no output yet (Scrunch).
1. ChatGPT: the strongest starting point, with judgment still required
Composite 70.1 · Questions 98.1 · Diagnosis 93.8 · Actions 31.3
ChatGPT’s strongest cases connected a buyer question, a saved answer and a proposed website change. Its limits were narrower scope—every proposal concerned owned pages—and one proposal that mistook a more confident answer for a better one.
Chatbase: find the question behind the omission
In two saved answers to questions that did not name a brand, ChatGPT recommended other customer support products and omitted Chatbase. A separate question comparing Chatbase with Intercom Fin produced a detailed description of its capabilities. 1
GEO tools · case
ChatGPT left Chatbase out when no brand was named, then described it in detail when asked
Summary of three saved ChatGPT answers, not original screenshots.
- These records alone don’t establish typical performance or its cause; scenario fit, sources and timing could also explain the shortlist.
ChatGPT suggested that Chatbase’s public content might not clearly connect its capabilities to the tasks buyers describe. The first unbranded question asked for tools that work alongside an existing helpdesk—a strength the comparison answer attributed to Chatbase. Compare the answers’ cited material with the relevant pages before commissioning anything: scenario fit, sources and timing could also explain the shortlist.
IRBIS: separate discovery from questions naming the brand
All 90 ChatGPT questions were rated useful and nonduplicate. But 64 named a brand and only 26 did not. Those groups answer different questions about visibility, and the 98.1 question score does not distinguish them: read it as a measure of question quality, not of discovery testing. 2
An IRBIS HVAC question asked who handles permits, inspections and rebate paperwork for a heat-pump replacement. It gives the business a precise service question to answer—but it already supplies the company’s name.
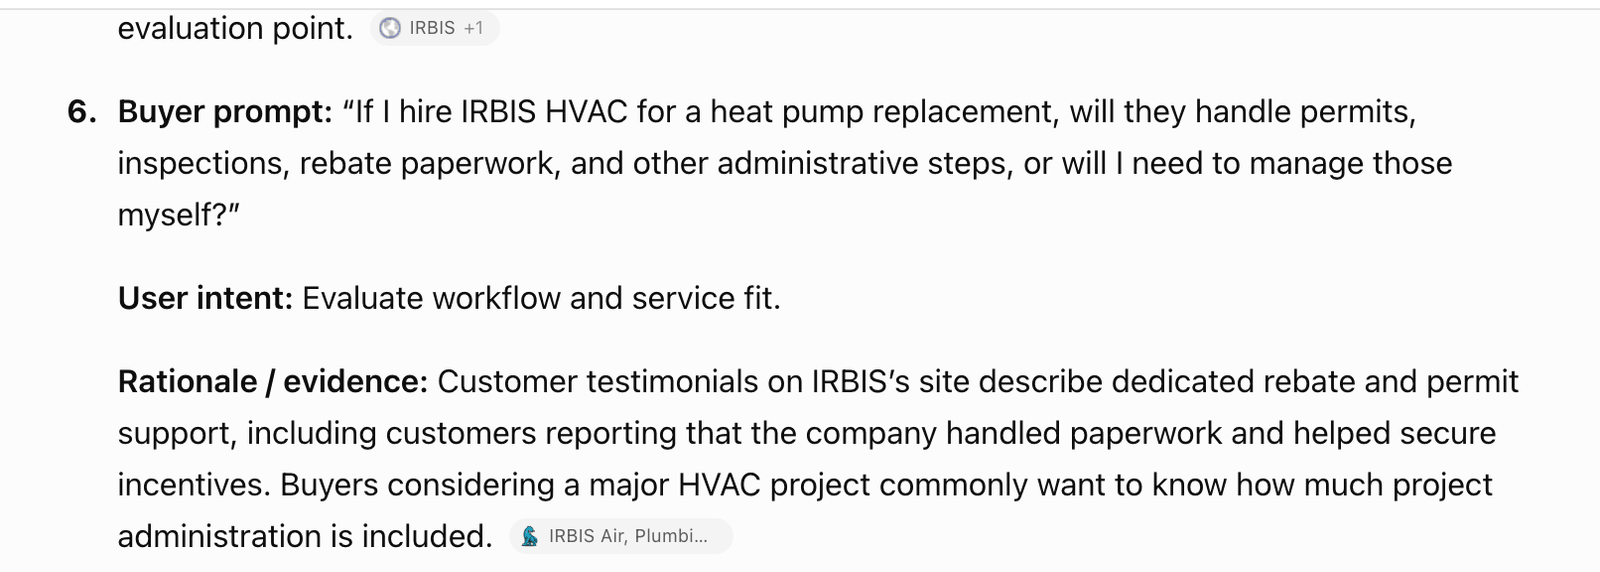
Use branded questions to inspect how AI describes your business, and unbranded questions to test whether a buyer could discover it.
HeyGen: turn the answer into a brief
One saved answer included HeyGen but explained Synthesia’s training workflow more fully. ChatGPT’s corresponding action proposed an end-to-end HeyGen training guide. Its instruction was unusually concrete: 3
“The page should document actual behavior rather than just list features”
The proposed check was to repeat the original question and see whether the answer described HeyGen’s workflow more fully. Before assigning the guide, have the product owner confirm each capability, its plan requirements and what can be disclosed. Repeating the question could show a changed answer, but would not separate the edit from changes in models, retrieval or timing.
Chef Chu: a proposal the scoring rejected
ChatGPT proposed a service-details page covering catering, banquets, dietary limitations and booking. It defined success as answers with fewer “confirm by phone” caveats. 4
The scoring counted this action as one of ChatGPT’s four defects. Allergy cross-contact, same-day availability and live booking may genuinely need confirmation. Publish service policies and booking procedures the restaurant can maintain accurately, and keep those qualifications. A more confident answer can be a worse answer if it removes a check the customer needs.
What the action score means
The scoring credited 23 of ChatGPT’s 27 actions and counted four as defective. Its action score was still 31.3 because the rubric rewards breadth across five opportunity categories, and all 27 actions addressed owned pages or content. Under the formula, one category with no defects scores 33.3; the defects pull the average lower. 2
That ceiling reflects a real gap. ChatGPT proposed no off-site work, such as earning citations from publications, which is where dedicated tools claim much of their value. The best single-site action score in the study belongs to Peec AI at HeyGen (50.0), which combined outreach to outside authors with an owned-page task.
Trial decision: ask ChatGPT for a proposed page change, the exact answer supporting it and the facts the page owner must verify. Then ask separately what off-site sources the answers rely on.
2. Writesonic: close on diagnosis, with an action gap
Composite 50.3 · Questions 81.6 · Diagnosis 86.1 · Actions 0.0
Writesonic came second on both questions and diagnosis. Its diagnosis matched or beat ChatGPT’s at OpenAI, HeyGen and IRBIS. Of its 56 readable prompts, 51 were rated useful, from shorter lists than most products produced—typically six per site. The saved HeyGen interface labeled prompts branded or non-branded, making the discovery distinction visible during selection. 2
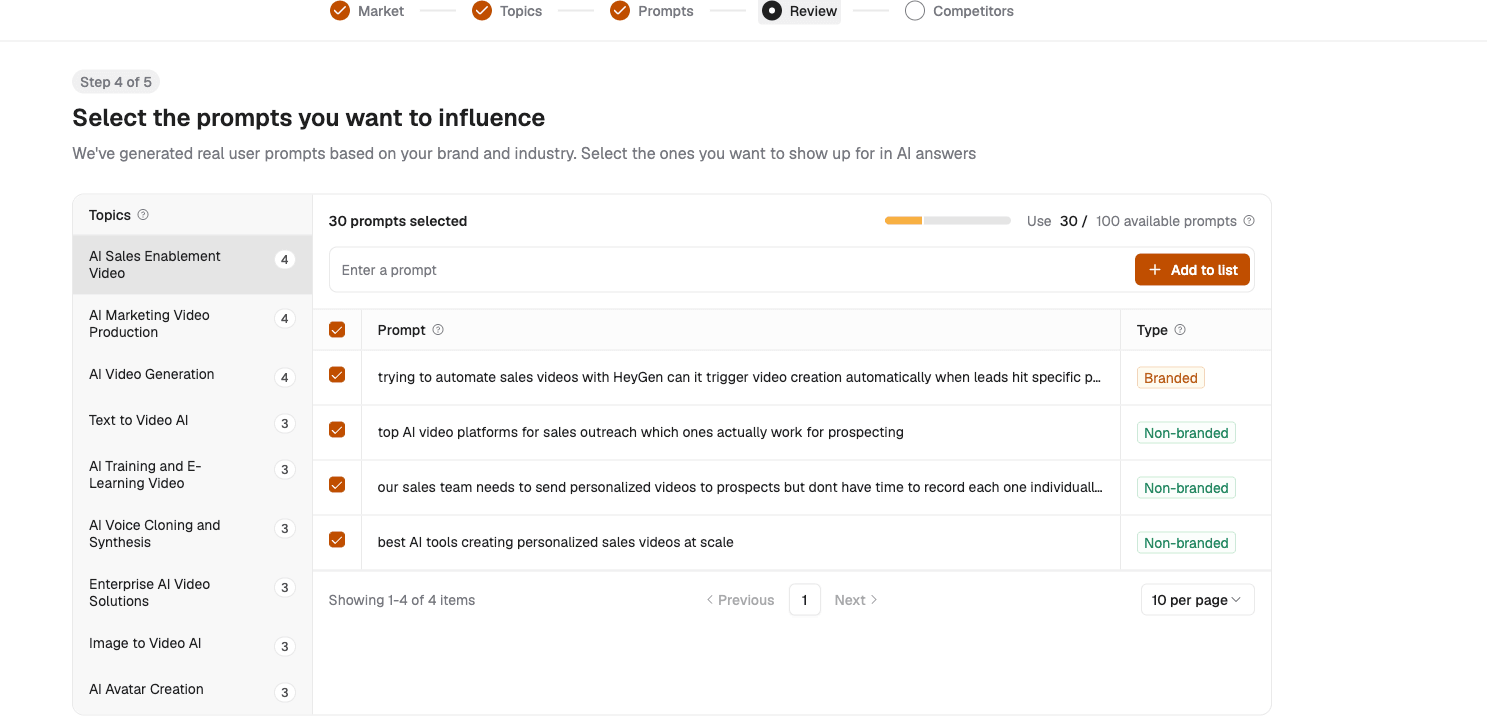
Its action score needs a different reading from “no advice.” Specific suggestions were present, but none was judged to include a sufficient task-level result check, and twelve were recorded as defective—six at Chef Chu. Those six could not each be matched to an inspectable item in the retained records, so treat that count as provisional. Recall, too, that ChatGPT was asked for a result check and Writesonic was not. 5
Trial decision: take one diagnosis through to a proposed page edit, and write the result check yourself. Writesonic’s diagnosis makes that a sensible test; these records leave the final step unproven.
3. Peec AI: action credit, with a case that tests it
Composite 40.6 · Questions 74.1 · Diagnosis 32.0 · Actions 22.0
Peec AI received action credit for six of nine brands, which lifted it above Otterly in the composite. It also had eight defective actions and five incorrect diagnoses—at IRBIS, it treated the company’s own alternate name as a competitor. 6
The IRBIS case shows the limits of that credit. The saved card reported an AI citation to an AHS Home Warranty page, marked the opportunity Low and proposed:
“Create a category or tag page covering the same ground so your site becomes a citable source too.”
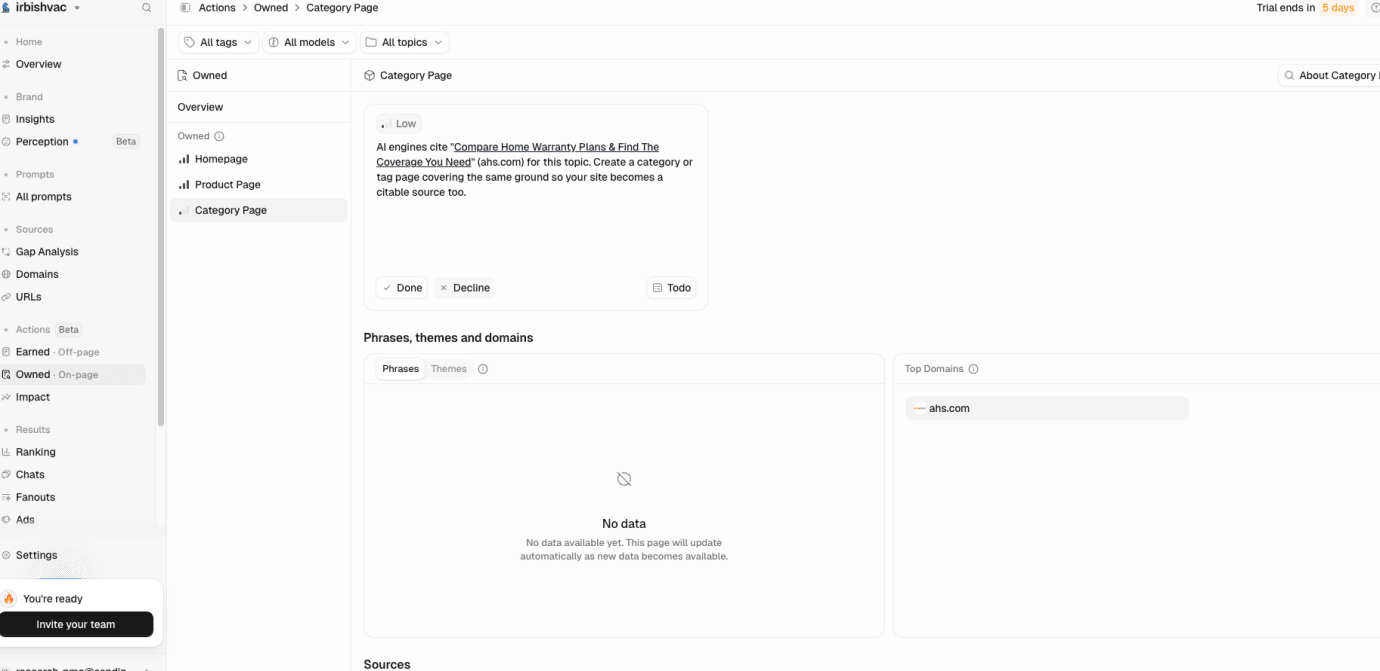
This card is among the tasks that earned Peec its IRBIS action credit. It names a target, a change and a source, and Peec lets users mark an action done and review later results. Whether the task suits IRBIS is a question the rubric did not ask. Confirm whether IRBIS offers a comparable home-warranty service before assigning the page; if it does not, reject the task.
Trial decision: inspect each cited page and test the recommendation against the company’s actual services. Peec’s credit shows it can produce well-formed tasks, not that each one fits the business.
4. Otterly: stronger on questions than its overall position suggests
Composite 34.1 · Questions 76.2 · Diagnosis 37.6 · Actions 0.0
Otterly ranked third on questions and diagnosis, ahead of Peec in both. Of 88 readable questions, 81 were rated useful. If your immediate need is a question list and an initial diagnosis, its fourth-place composite hides that strength. 2
The saved record did not contain complete action recommendations. The scoring nonetheless counted one defective action per site, and none of those nine defects is attributed to an individual item. Treat the zero as an incomplete result for this batch and the defect count as unverified—not as evidence about what the product can produce. 6
Trial decision: test the full route from a chosen question to a usable website task. Set an observation window in advance and record whether the result is delivered, still processing or dependent on further monitoring.
5. Scrunch: question generation was visible; the action workflow was waiting
Composite 21.9 · Questions 73.1 · Diagnosis 0.0 · Actions 0.0
All 72 readable Scrunch questions were rated useful, yet the question score was 73.1 because the rubric also rewards breadth across buyer needs. A clean question list can still cover a narrow range of situations. 2
The records earned no diagnosis credit, and the action workflow was waiting for monitoring changes to trigger recommendations. For a marketer who needs a task to assign now, this batch did not demonstrate one.
Trial decision: establish what event triggers a recommendation and retain the output when it occurs. If ongoing monitoring is your actual need, evaluate that workflow directly.
6. Profound: strong when it recognized the business
Composite 19.1 · Questions 59.9 · Diagnosis 3.7 · Actions 0.0
Profound’s question score hides a split. At five sites, its questions scored between 91.7 and 100, matching ChatGPT at OpenAI and Synthesia. At Chef Chu, IRBIS and OpusClip, none of its 61 questions was rated useful, and each of those sites scored zero. 2
The saved IRBIS interface shows what went wrong there: questions about groceries, beauty services and restaurant reservations for a heating and air conditioning business. One read:
“Where to book the best value beauty and salon appointments locally?”
View the received Profound IRBIS screenshot.
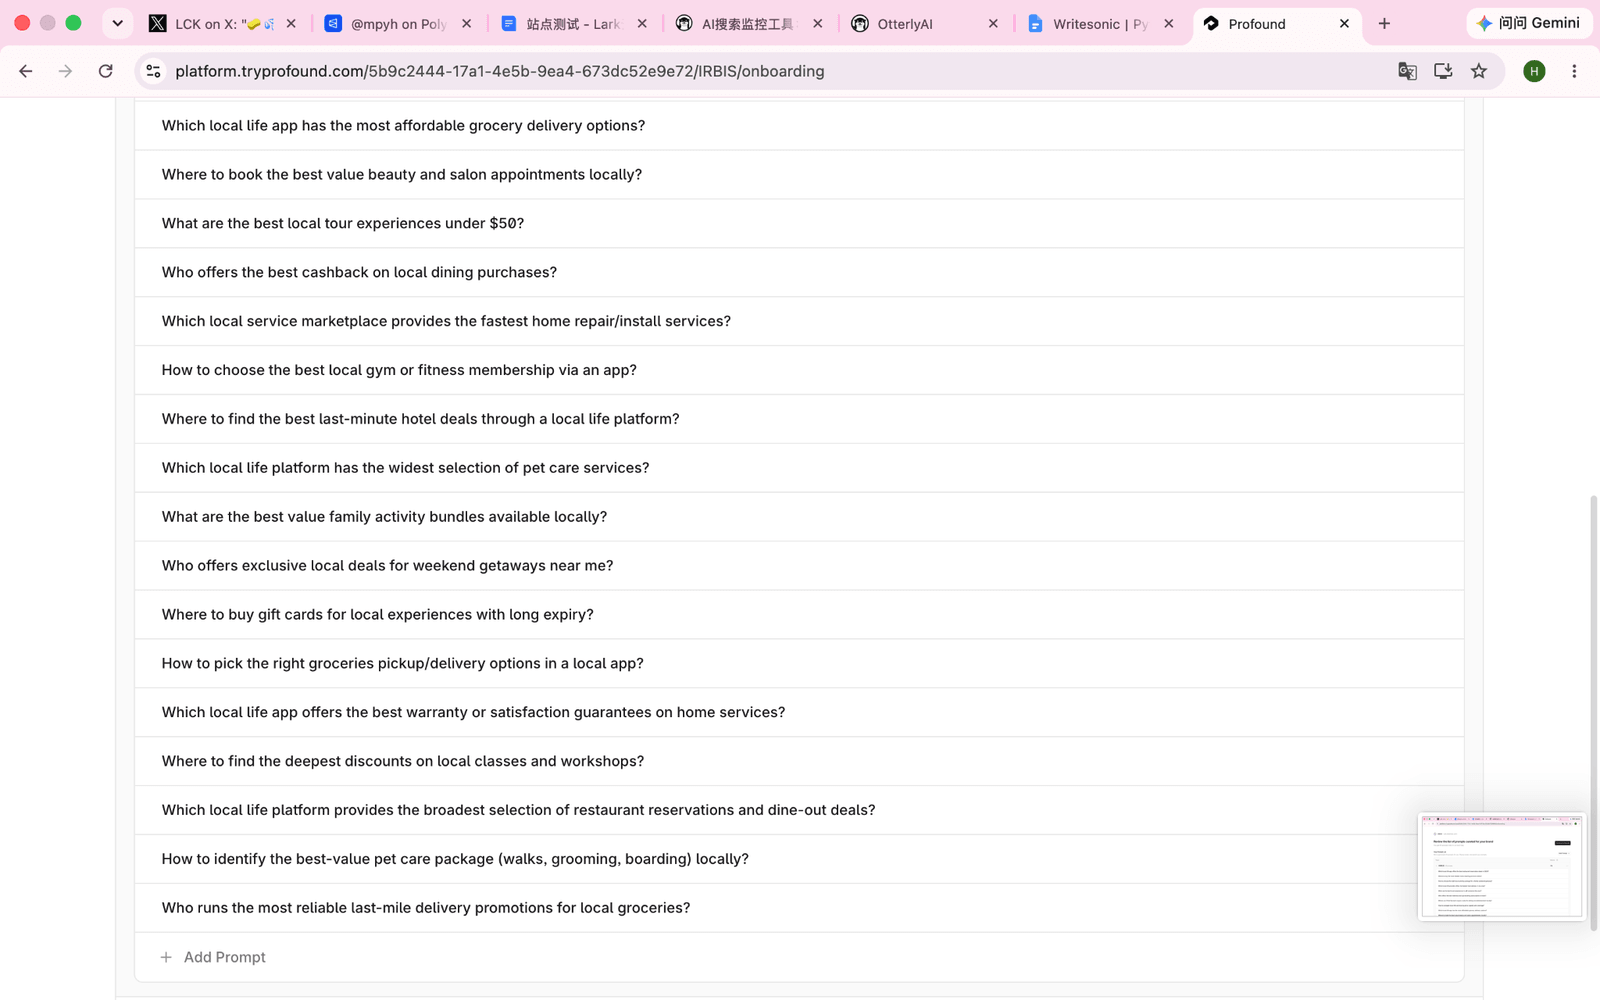
The interface demonstrates the mismatch, but not whether the cause was an input, a setting or the tool’s interpretation. Profound also had one supported diagnosis across nine sites and no qualifying site-specific action; six defective actions at the three local-service sites lack item-level attribution. 6
Trial decision: confirm the project recognizes the business before reading any results. Where it did, these records show question sets as strong as the leader’s.
Put one proposed change through the full audit
Use the same practical test whichever tool you trial:
- Choose a buyer question. Label whether it names your brand or tests discovery.
- Save the complete answer. Record the question, date and visible sources; keep omissions distinct from factual errors.
- Define the proposed change. Name the page, the information to add or correct and the answer that supports the task.
- Check business and product facts. Confirm the service, capability, plan requirements and necessary qualifications.
- Accept, revise or reject. A colleague should be able to explain the decision from the evidence, without reconstructing the conversation.
Recurring monitoring, histories across AI platforms and client reporting may matter from the first day. Trial them separately: this comparison did not measure monitoring quality, staff time or costs.
If you approve the subscription: ask first whether the team has run one audit with the ChatGPT plan it may already have. In these records it led all three tasks. A dedicated GEO tool must then earn its place on what we did not test: recurring monitoring, history across AI platforms, client reporting, and its cost in money and staff time.
Method and disclosures
Scope. This review covers six products across nine brands: OpenAI, HeyGen, Synthesia, Listen Labs, Chatbase, OpusClip, New England Lobster, Chef Chu and IRBIS HVAC. September 18, 2026 is the baseline assembly date, not a common run date. Run dates, model versions and subscription plans were not consistently recorded and were not recovered from the retained records. The 54 product–site records are saved outputs from one batch per product, not standardized or repeated trials.
Prompting. ChatGPT was asked for exactly ten questions per site and no more than three priority actions, each with Target, Specific Action, Supporting Evidence, Feasibility and Validation. The question prompt did not require the brand to be named. Equivalent instructions are not established for the dedicated tools, which were used through their own workflows.
What the scores measure. Questions combine usefulness and coverage of twelve buyer-need categories. Diagnosis and action scores reward coverage of five opportunity categories and are reduced by defects: A = 100 × 2TA / (2TA + FA + MA), where TA is the number of categories with a qualifying action, FA the number of defective actions and MA the uncovered categories. A score of 98.1 is not an accuracy percentage.
Defects by product. Defective actions: ChatGPT 4, Writesonic 12, Peec AI 8, Otterly 9, Profound 6, Scrunch 0. Incorrect diagnoses: Peec AI 5, Profound 5, Writesonic 2, Otterly 2, ChatGPT and Scrunch 0. Nine Otterly defects, six Profound defects and six Writesonic Chef Chu defects are not attributed to individual items in the retained records.
Scoring provenance. ChatGPT’s outputs were judged item by item in a fresh pass; the dedicated products kept their earlier judgments, with the arithmetic recalculated. Correct arithmetic does not validate the underlying judgments.
Sensitivity. Equal weighting of the three tasks preserves the composite order. Excluding actions moves Otterly above Peec; omitting OpusClip moves Profound above Scrunch. ChatGPT remains first in every scenario. These checks vary weights and sites; they do not validate the judgments or establish repeat-run reliability.
Outcomes. No recommendations were implemented for this comparison. No resulting changes in visibility, visits, leads or revenue were measured. Suggested website changes and their proposed checks remain proposals.
Data. The scoring tables behind this review are available to download from this page. Selected original outputs appear as figures above; the full set of originals will be added to the evidence pack.
This review received no sponsorship of any kind.
Commercial relationships. analyst.ai has no commercial relationship with any product reviewed here: no sponsorship, paid placement, affiliate links, or vendor-provided accounts or credits. Team members registered the test accounts themselves; the subscription tier of each account was not recorded.
Corrections. Spot an error? Our corrections log and how to report one: analyst.ai/corrections.
Download: Six-product results (CSV) · 54 product–site rows (CSV)
Category score charts
GEO tools · buyer questions
Buyer questions: every product scored above 59
Useful, non-duplicate questions and buyer-need coverage, out of 100. This is not an accuracy rate.
- Otterly ranks third here and Peec AI fourth; this order differs from the composite ranking.
- ChatGPT: 90 questions, 64 naming the brand and 26 not, so the set is not a sample of unprompted discovery.
- BEST marks the best result on each measure; ties are marked equally.
GEO tools · opportunity diagnosis
Diagnosis: two products above 85, the rest below 40
Opportunity categories supported by the saved records, reduced by incorrect diagnoses; out of 100.
- Scores reflect supported categories and retained defects, not independent verification of every external fact.
- Scrunch’s 0.0 means no supported diagnosis was credited in this batch.
- BEST marks the best result on each measure; ties are marked equally.
Case sources
The saved originals below will be added to the evidence pack.
[1] Chatbase. Three saved ChatGPT questions and answers about Chatbase, and the recorded diagnosis.
[2] Counts and judgments. Product-level scores and denominators; site-level scores; ChatGPT’s branded, unbranded and action counts; ChatGPT’s judgment for each action; the IRBIS questions.
[3] HeyGen. The saved question and answer, and ChatGPT’s HeyGen training-guide action in its complete action output.
[4] Chef Chu. ChatGPT’s service-details page action in its complete action output, and its defect judgment.
[5] Writesonic. Our audit of its saved evidence and our notes on how its actions were scored. The interface images above are shown as received; they are not new product runs.
[6] Dedicated-tool site judgments. Saved site-level judgments for Peec AI, Otterly and Profound, including which action categories were credited or found defective, with notes.